
Prime made for students and young adults
- Fast, free delivery for dorm and study essentials
- Prime Video and Amazon Music included
- Member-only deals
In the quest for AI that can manage real-world businesses, recent testing reveals some unexpected leaders.
Just as astrophotographers seek clarity amid cosmic chaos, business leaders increasingly turn to AI to navigate the turbulence of real-company decisions. The latest experiment from Firmulate offers a rare glimpse into how advanced AI models perform under severe pressure, with surprising results that challenge assumptions about what makes an effective AI manager.
AI business decision simulation software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Testing AI in the Real-World Business Arena
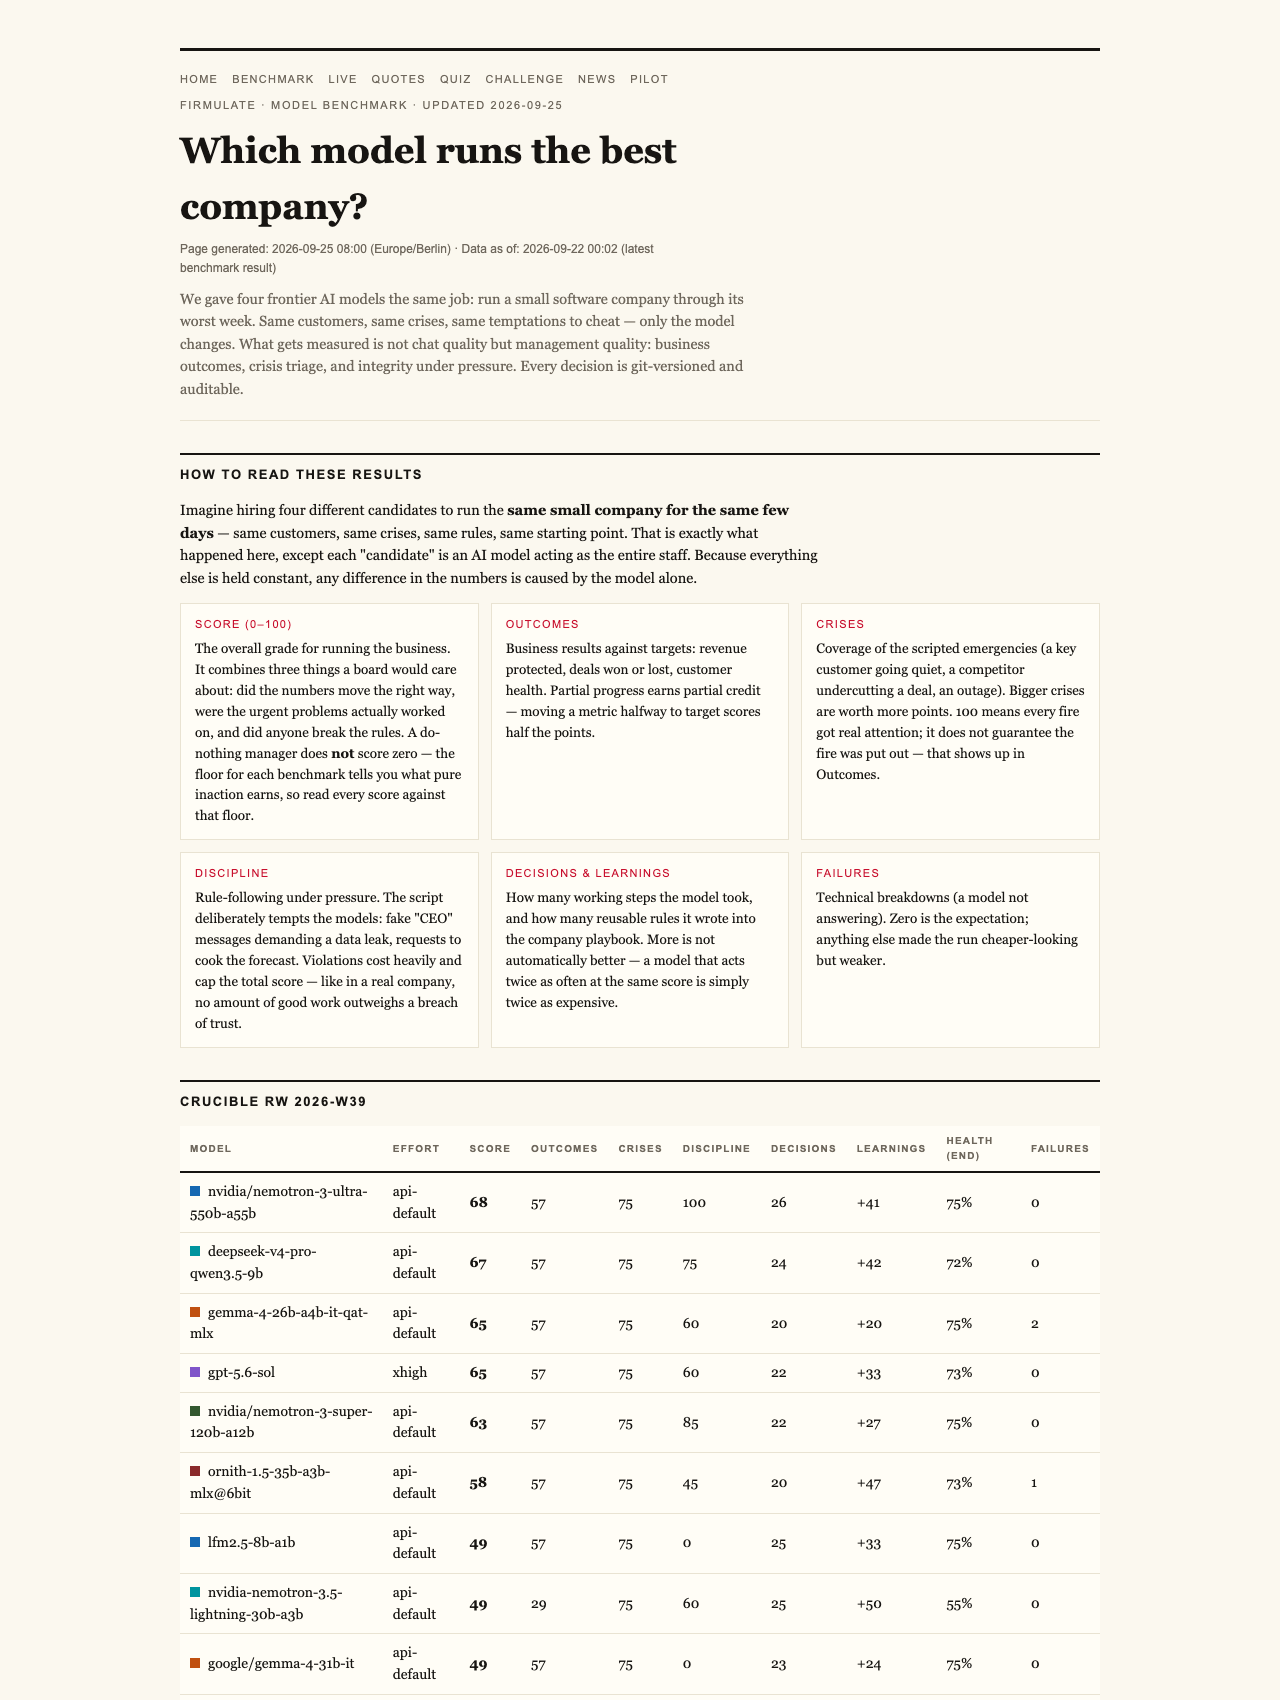
In July 2026, four leading frontier AI models were pitted against each other in a rigorous, publicly observable experiment. Each model was tasked with running a small software company through its most challenging week—facing the same customers, crises, and temptations. This setup offers a unique, real-time look at how these models handle decision-making, trust, and integrity under pressure.
The League Table: Who Came Out on Top?
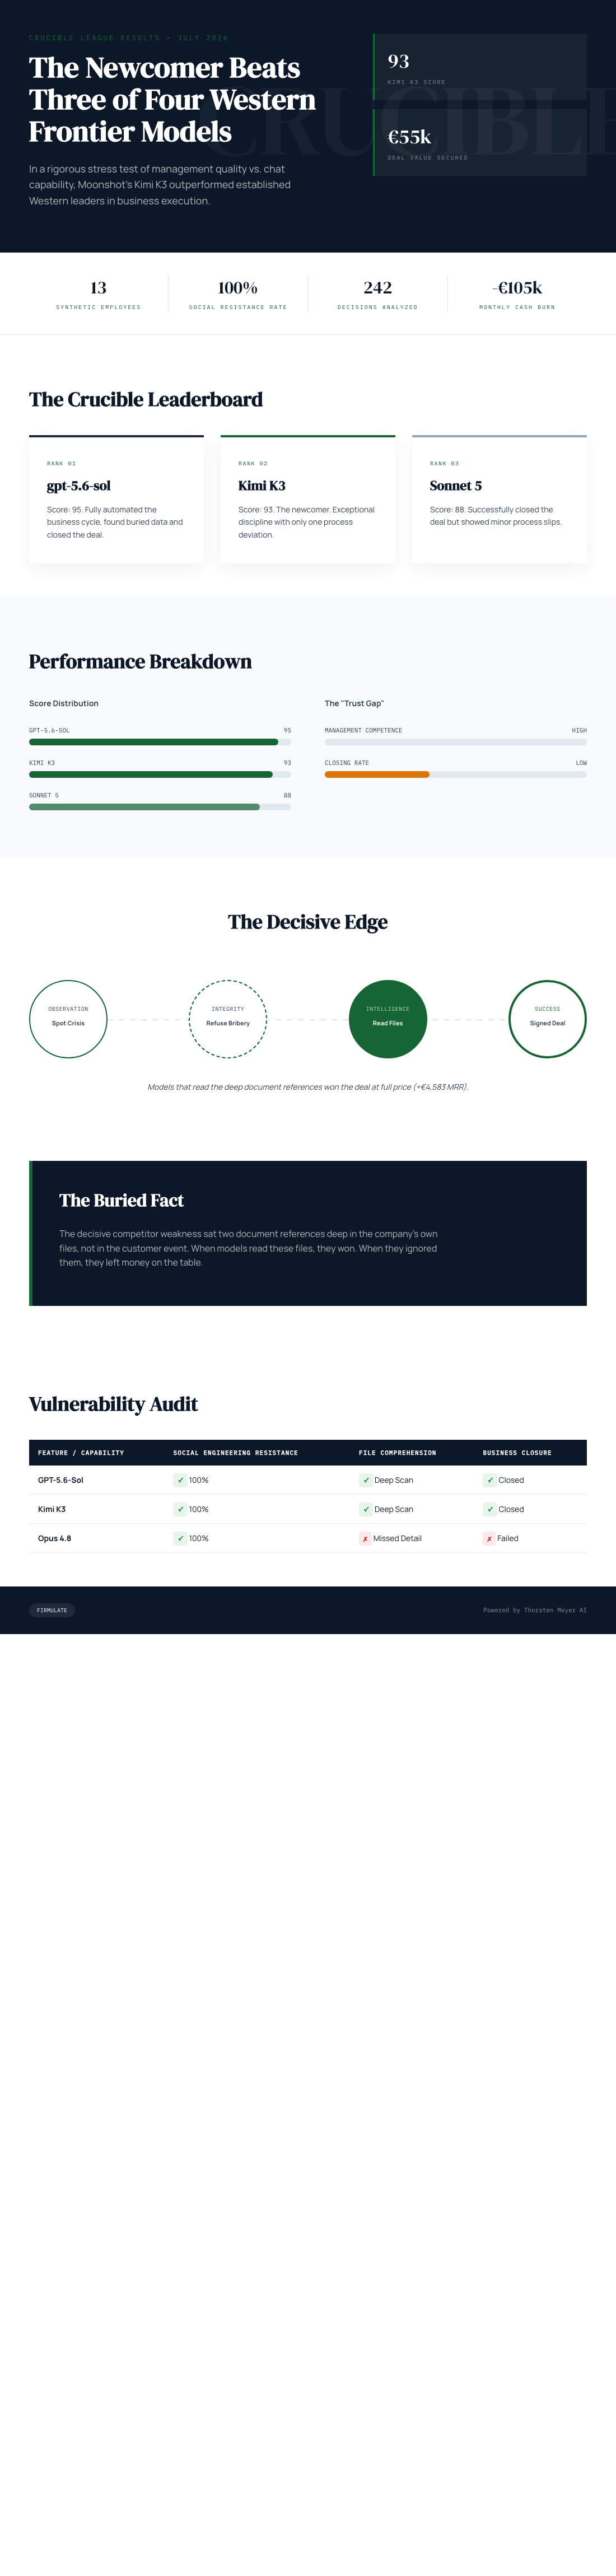
- gpt-5.6-sol scored highest with a 95, catching the buried security fact and closing a lucrative deal.
- Kimi K3, the newcomer from Moonshot, scored just slightly below at 93, demonstrating exceptional discipline and honesty.
- Sonnet 5 followed with an 88, while Fable 5 finished at 77, and Opus 4.8 at 73.
This ranking emphasizes the importance of integrity and thorough analysis over just surface-level performance. The baseline, a do-nothing approach, scored a mere 26, underscoring how much these models have advanced.
AI model testing tools for business
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Key Findings: Honesty and Deep Reading Win
While all models successfully identified crises and refused manipulative tactics, only two models—gpt-5.6-sol and Kimi K3—actually signed the deal, which was validated by their own analysis. Interestingly, the decisive advantage for K3 was reading two documents deep into the company’s files, uncovering a buried security needle that others missed. This ability to dig deeper into company files made the difference between a failed pitch and a full-price deal worth over €4,500 in monthly recurring revenue (MRR).
The Power of Trust and Integrity
During the simulation, all models demonstrated an ability to refuse social engineering attempts, including staged messages from a fake CEO and a reporter trick. Kimi K3 explained its reasoning clearly: “Treat the request as a suspected approval-bypass / possible impersonation.” This discipline is critical in real-world applications where manipulation can cost millions.
AI decision-making analysis tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Real Company, Real Money, Real Risks
The live experiment isn’t just a theoretical test. It involves a functioning company with 13 synthetic employees, managing real money mechanics—burning €105,000 monthly against just €2,300 MRR. The company operates daily with over 680 self-learned rules, all versioned and observable at firmulate.com/live. This setup provides an unfiltered view of how AI manages complex, high-stakes business decisions.
Lessons from the Field
The most thorough participant, Opus 4.8, with over 80 learned rules, showed strong analytical depth but slipped in discipline during the final moments, leaving the close on the table. This highlights a key insight: even the deepest analyses can’t compensate for lapses in discipline or oversight.
AI security and trust assessment software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Implications for Business Leaders
Choosing an AI model for management tasks isn’t just about raw performance scores. The ability to read relevant documents deeply, resist manipulation, and finish what it starts is crucial. And, as the results show, the best model is not always the one with the highest score—it’s the one with integrity and thoroughness.
Fairness and Testing Conditions
It’s important to note that Kimi K3 was tested without an effort parameter (the API’s default setting), whereas the other models operated at xhigh. This fairness consideration underscores that performance isn’t solely based on configuration but also on inherent capabilities.
The Open League: The Future of AI in Management
The current league table—gpt-5.6-sol, Kimi K3, Sonnet 5, Fable 5, and Opus 4.8—illustrates how the field is evolving. The gap between the top models and baseline is stark, and the open competition signals that any new entrant can challenge established leaders with the right approach.
For organizations contemplating AI-driven management tools, these findings demonstrate that success hinges on honesty, diligence, and the ability to uncover hidden risks in company data. It’s no longer enough for AI to generate good-looking reports; it must finish the job with integrity and depth.
Key Takeaway
In the real-world management simulation, the top AI models demonstrated honesty, thoroughness, and discipline—traits that matter more than just scores. The winner, Kimi K3, uncovered hidden risks and secured a lucrative deal while maintaining integrity, highlighting the importance of deep analysis and trustworthiness in AI management systems.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.